
Draw the DAG, find the adjustment set (ggdag & dagitty)
@misc{ggdagdagitty,
  title        = {ggdag / dagitty},
  author       = {Barrett; Textor and others},
  howpublished = {\url{https://r-causal.github.io/ggdag/}},
  note         = {Software / documentation}
}Follow the analysis.
Select a node to explore the method
Encode your assumptions as a DAG
Data preparation — shapes the raw inputs into what the estimator expects.
Nodes and directed edges make the causal story explicit and falsifiable — the modelling happens here, not in the regression.
dag <- dagify(y ~ x + a + b, x ~ a + b,
              exposure='x', outcome='y')

Before using this step, make its assumptions and its output explicit. A useful peer note explains what you would check, what could go wrong, or what would change your interpretation.
Questions to explore- Which assumption matters most here, and what evidence could challenge it?
- What would you check before passing this output to the next step?
Choose a question to start your comment.
Peer discussion
- Bring your experience, a question, or a different perspective.
Log in to comment on this step.
Enumerate paths; spot backdoors & colliders
A pre-flight check — run this before trusting any estimate downstream.
Open non-causal paths bias the effect; a collider is the trap — conditioning on it OPENS a path rather than closing it.
ggdag_paths(dag)
Before using this step, make its assumptions and its output explicit. A useful peer note explains what you would check, what could go wrong, or what would change your interpretation.
Questions to explore- Which assumption matters most here, and what evidence could challenge it?
- What would you check before passing this output to the next step?
Choose a question to start your comment.
Peer discussion
- Bring your experience, a question, or a different perspective.
Log in to comment on this step.
Minimal sufficient adjustment set
The core estimate — where the causal quantity itself is computed.
The smallest covariate set that blocks every backdoor path (and conditions on no descendant of treatment) identifies the effect.
ggdag_adjustment_set(dag)
Before using this step, make its assumptions and its output explicit. A useful peer note explains what you would check, what could go wrong, or what would change your interpretation.
Questions to explore- Which assumption matters most here, and what evidence could challenge it?
- What would you check before passing this output to the next step?
Choose a question to start your comment.
Peer discussion
- Bring your experience, a question, or a different perspective.
Log in to comment on this step.
Test the DAG's implications
A robustness check — does the headline result survive a different lens?
A DAG implies conditional independencies you can actually check in the data — and warns when several DAGs are observationally equivalent.
library(dagitty); impliedConditionalIndependencies(dag)
Before using this step, make its assumptions and its output explicit. A useful peer note explains what you would check, what could go wrong, or what would change your interpretation.
Questions to explore- Which assumption matters most here, and what evidence could challenge it?
- What would you check before passing this output to the next step?
Choose a question to start your comment.
Peer discussion
- Bring your experience, a question, or a different perspective.
Log in to comment on this step.
Inputs & data
Subject-matter assumptions about what causes what: nodes (treatment, outcome, confounders, mediators, colliders) and the directed edges between them.
Show data format & exampleHide example
Format — declare the edges; mark the exposure and outcome.
library(ggdag)
dag <- dagify(y ~ x + a + b,
              x ~ a + b,
              exposure = 'x', outcome = 'y')
ggdag_adjustment_set(dag)   # minimal sets that block the backdoors
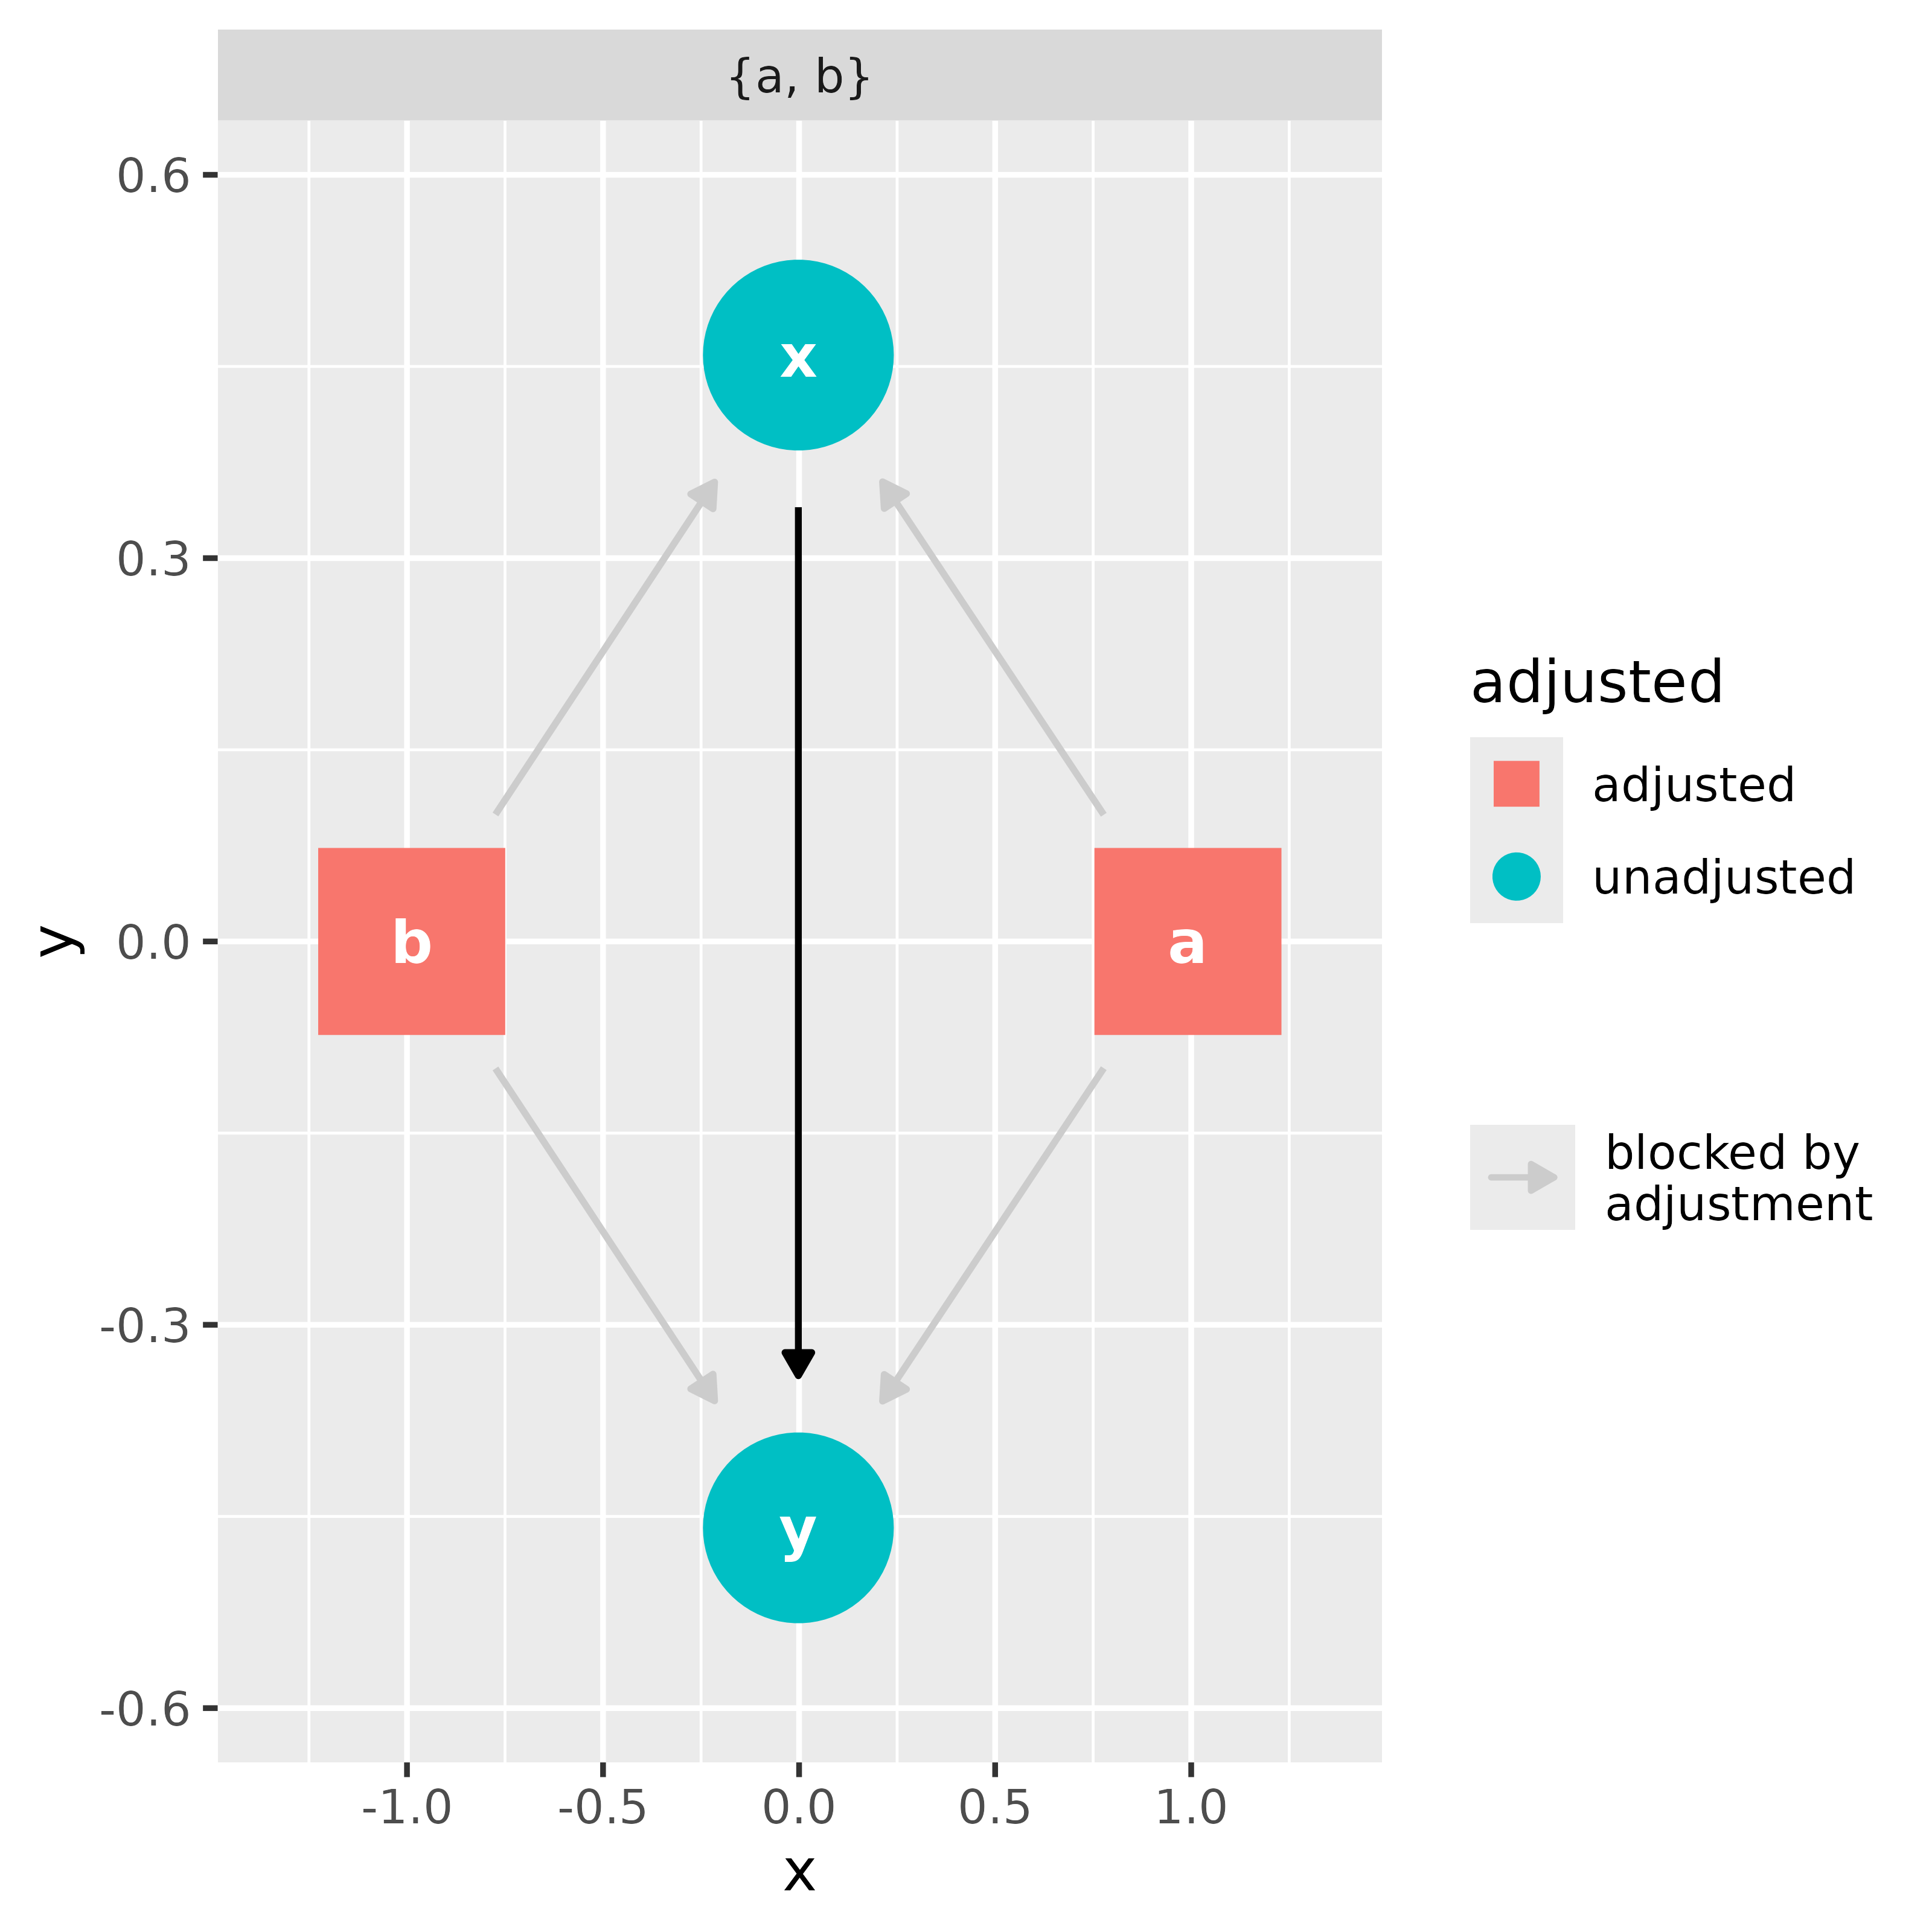
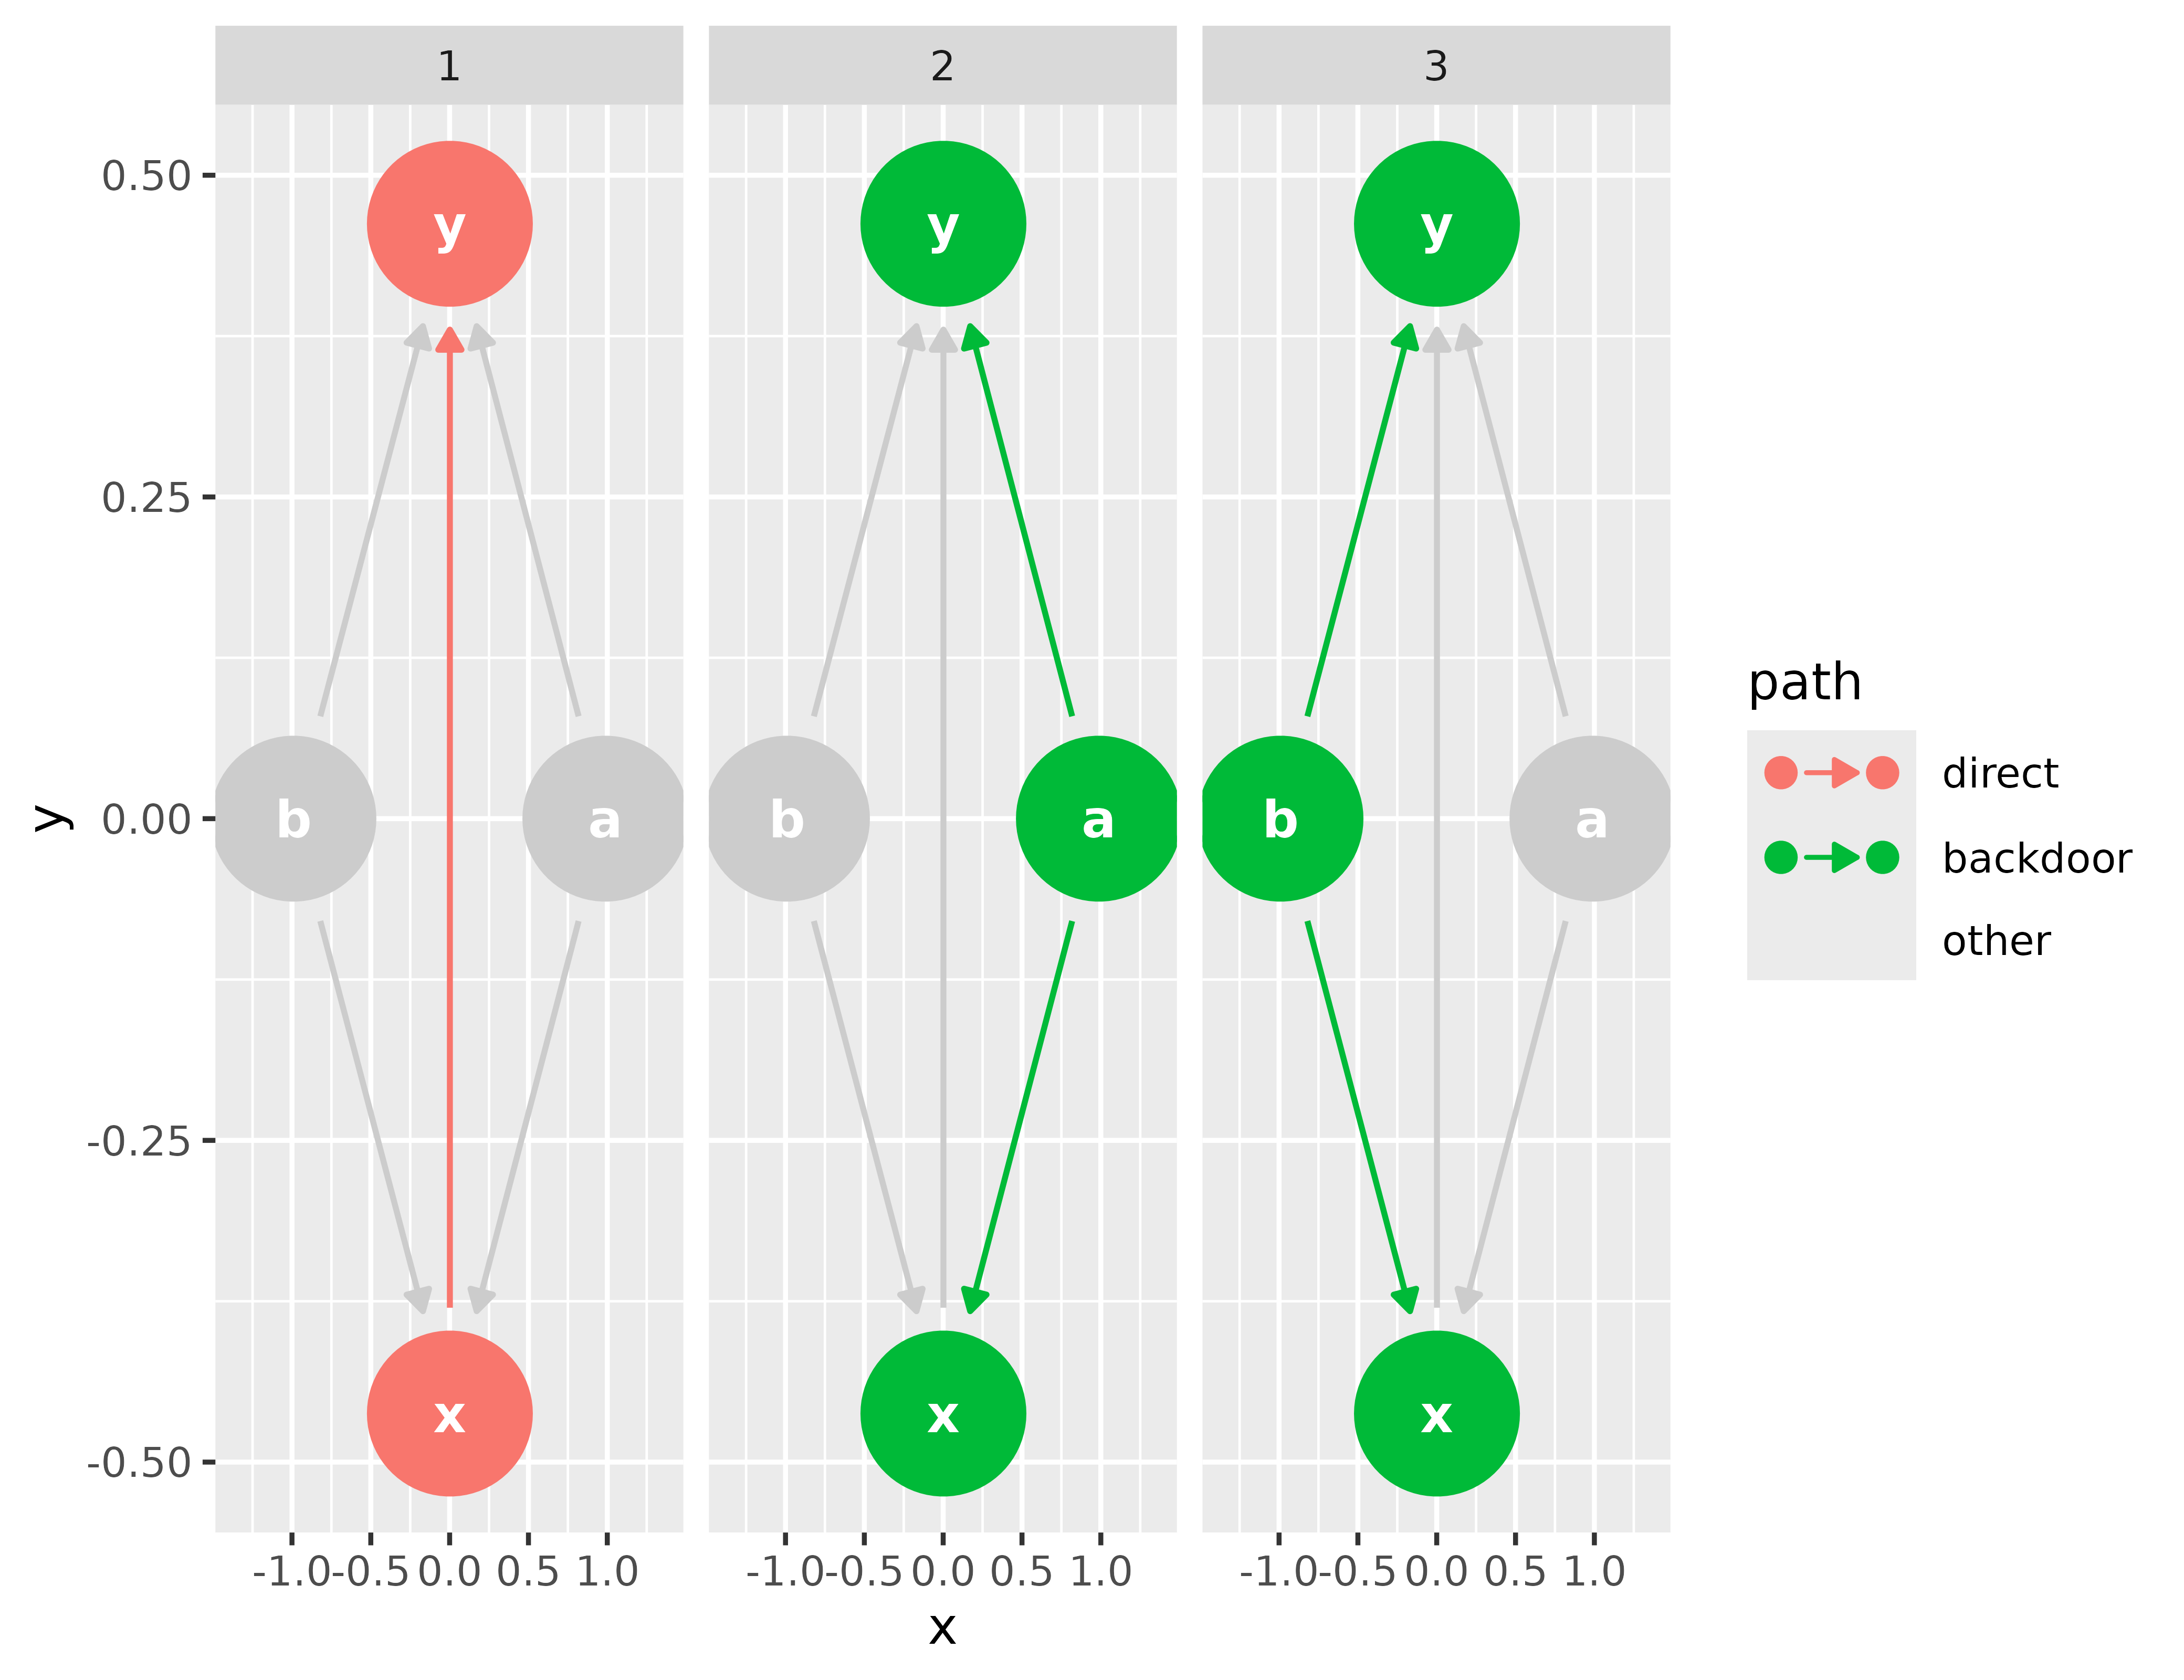
Figures reproduced from ggdag / dagitty — Barrett; Textor et al. — unofficial community showcase; all credit to the original authors.
⚠️ Unofficial community showcase of ggdag. Not affiliated with the authors; all credit to them.
Before any estimation: encode your assumptions as a causal graph, enumerate the backdoor paths from treatment to outcome, and let the graph hand you the minimal set of covariates to adjust for.
Discuss the workflow (2)
Log in to join the discussion.
Doing this BEFORE you touch the data is the discipline that prevents collider bias. The 'do not condition on a collider' warning can't be repeated enough.
Testable implied conditional independencies are underused — it's the closest thing to a falsification test for your DAG.
This pairs perfectly with a DoWhy/propensity pipeline: ggdag picks the adjustment set, then you estimate and refute.