
Simulation-based inference for any model (clarify)
Follow the analysis.
Select a node to explore the method
Fit any regression model
The core estimate — where the causal quantity itself is computed.
Fit the substantive model — here a logit for the probability of positive earnings with a treatment-by-covariate interaction.
# Install:  install.packages("clarify")
library(clarify)
fit <- glm(re78 > 0 ~ treat * (age + educ + married),
           data = lalonde, family = binomial)

Before using this step, make its assumptions and its output explicit. A useful peer note explains what you would check, what could go wrong, or what would change your interpretation.
Questions to explore- Which assumption matters most here, and what evidence could challenge it?
- What would you check before passing this output to the next step?
Choose a question to start your comment.
Peer discussion
- Bring your experience, a question, or a different perspective.
Log in to comment on this step.
Simulate the coefficient distribution
Uncertainty quantification — standard errors, intervals, and aggregation.
Draw 1000 coefficient vectors from the model's (approximately normal) sampling distribution.
sim_coefs <- sim(fit, n = 1000)
Before using this step, make its assumptions and its output explicit. A useful peer note explains what you would check, what could go wrong, or what would change your interpretation.
Questions to explore- Which assumption matters most here, and what evidence could challenge it?
- What would you check before passing this output to the next step?
Choose a question to start your comment.
Peer discussion
- Bring your experience, a question, or a different perspective.
Log in to comment on this step.
Average marginal effect of treatment
Reporting — turn the numbers into a figure or table a reader can act on.
Push every draw through the prediction function and average to get the AME with a percentile interval.
est <- sim_ame(sim_coefs, var = "treat", verbose = FALSE)
summary(est)
Before using this step, make its assumptions and its output explicit. A useful peer note explains what you would check, what could go wrong, or what would change your interpretation.
Questions to explore- Which assumption matters most here, and what evidence could challenge it?
- What would you check before passing this output to the next step?
Choose a question to start your comment.
Peer discussion
- Bring your experience, a question, or a different perspective.
Log in to comment on this step.
Inputs & data
A fitted regression model (lm/glm/…) and the data used to fit it.
Show data format & exampleHide example
| re78>0 | treat | age | educ | married |
|---|---|---|---|---|
| 1 | 1 | 37 | 11 | 1 |
| 0 | 0 | 22 | 9 | 0 |
| 1 | 1 | 30 | 12 | 1 |
| 0 | 0 | 45 | 14 | 0 |
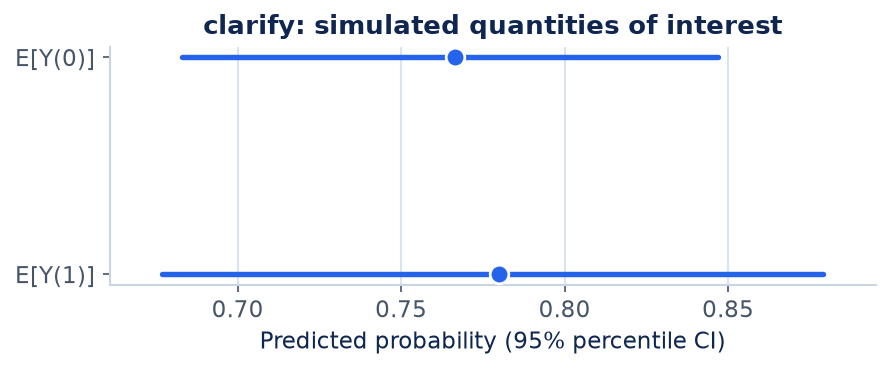
Result figure rendered by StatsOtter from the package's documented example — unofficial community showcase; all credit to the original authors.
The estimate
\hat\theta=\frac1S\sum_{s=1}^{S} g(\tilde\beta_s),\quad \tilde\beta_s\sim\mathcal N(\hat\beta,\widehat{\mathrm{Var}}(\hat\beta))
⚠️ Unofficial community showcase of clarify (docs). Not affiliated with the authors — all credit to Noah Greifer, Steven Worthington, Stefano Iacus & Gary King; this summarizes public documentation.
What it does. clarify is the modern successor to King, Tomz & Wittenberg's Zelig idea: after you fit any regression, it post-processes the model into substantively meaningful quantities (expected values, average marginal effects, first differences) with uncertainty from parameter simulation instead of the delta method.
How it works. sim() draws many coefficient vectors from the model's sampling distribution; sim_ame() / sim_setx() push each draw through the prediction function and average, giving a simulation distribution for the quantity of interest; summary() reports its mean and percentile interval. This sidesteps fragile delta-method approximations for nonlinear models.
Assumptions. The model is correctly specified and its coefficient sampling distribution is approximately multivariate normal (or you supply a bootstrap).
What you get — Simulation-based point estimates and percentile confidence intervals for predictions and average marginal effects.
Example output
         Estimate 2.5 % 97.5 %
E[Y(0)]    0.7666 0.683  0.847
E[Y(1)]    0.7799 0.677  0.879

Using 1000 simulated values per estimate.
Discuss the workflow (0)
Log in to join the discussion.